One command. Every Apple Silicon Mac.

Run local coding models on the Mac you have.

Saetta runs a local LLM for coding on Apple Silicon: an inference engine in C and hand-written Metal for Qwen3.8 models. It picks the model that fits your Mac, and Claude Code, pi and opencode use it like a cloud API, offline, with your code never leaving the machine.

Qwen3.8-Flash-Next Coder on an M5 Max, 128 GBsimulated replay

          
Claude Codepiopencode
agents found on this Mac
/v1/chat/completions/v1/messages
OpenAI and Anthropic APIs on 127.0.0.1:8080
Runs on M1M2M3M4 M5 neural accelerators 32 GB or more
Benchmarks

Saetta against Strata, the established engine

The same six coding-agent requests (4K to 64K-token prompts, a follow-up turn, a tool-call edit), one engine at a time on an M5 Max with 128 GB. The Coder pack finishes 1 s ahead of Strata; the full pack is 2 s behind and answers faster. Every number has a log.

Six requests, total seconds

Qwen3.8-Flash-Next, lower is better

Saetta fullSaetta CoderStrata (UD-Q4_K_XL)
Saetta full79.6
Saetta Coder76.5
Strata77.5
seconds, from 0

Answer speed on a code edit

400 tokens out, tokens/s, higher is better

Saetta fullSaetta CoderStrata
Saetta full142
Saetta Coder139
Strata130
tokens/s, from 0
Prompt reading
1,600 to 1,950 tokens/s with Flash-Next
Answers
66 to 85 tokens/s; 142 on a code edit with speculation
Follow-up turn
0.2 s to the first token on a 16K conversation
64K prompt
37.3 s to the first token with the Coder pack, Strata 39.6
Qwen3.8-27B
prompts at 940 tokens/s (4K) to 787 (64K)
27B TURBO
19 ms per token with its draft head, 85% of drafts accepted
8-bit quality
mean KL 0.001 against BF16 on Qwen3.8-27B
Context
204,800 tokens on 128 GB, sized down to fit smaller Macs
All results and method
Capabilities

What you get

Choose a model
   coder           downloaded, recommended 
    full            105 GB
    27b-turbo       20 GB
    27b-4bit        16 GB

Choose a coding agent
  > Claude Code     installed

One command to start

saetta shows the models that fit, downloads the one you pick, finds your agent or installs it, and starts it pointed at the local server.

this Mac: 36 GB

ok  27b-4bit        needs 32 GB
ok  27b-turbo       needs 36 GB
--  27b-8bit        needs 48 GB
--  coder           needs 96 GB

context: 37,888 tokens

Fits the Mac you have

Packs that cannot run are refused before they load, and the context is sized to the memory left. The M5's neural accelerators read prompts fastest; earlier chips run the same kernels.

turn 1   15,867 tokens   8.7 s
         reply saved as a restore point
turn 2   +84 new tokens  0.2 s
         the rest comes from the cache

new session, same system prompt:
         shared prefix   reused

Reads only what is new

Follow-up turns and new sessions reuse what the server already read, so agents answer in a fraction of a second instead of re-reading the conversation.

POST /v1/chat/completions   OpenAI
POST /v1/messages           Anthropic
GET  /v1/models

streaming, tool_calls,
reasoning_content, LoRA per request

Speaks both APIs

OpenAI chat completions and Anthropic Messages with streaming, tool calls and reasoning. Point any agent or SDK at 127.0.0.1:8080.

draft head   proposes the next tokens
trunk        checks them in one pass
27B TURBO    85% of drafts accepted

code edit    142 tokens/s
27B TURBO    19 ms/token

Guesses ahead

Speculative decoding with each model's own draft head, plus prompt lookup for code that repeats what is already in context. Same output as plain decoding.

kernels      C host + hand-written Metal
binary       one, no Python
verify       7/7 reference tests per commit
layers       numpy oracle, every layer
logits       max rel err 6.7e-7

Checked, layer by layer

Every model is verified against a numpy reference at every layer before a change lands, and every speed number comes from a recorded benchmark.
Models

Pick by your Mac's memory

PackModelOn diskMac memory
coderQwen3.8-Flash-Next, 256 experts pruned for code, the fastest for agents76 GB96 GB
fullQwen3.8-Flash-Next, all 512 experts105 GB128 GB
27b-turboQwen3.8-27B TURBO fine-tune, shorter thinking, with its draft head20 GB36 GB
27b-8bitQwen3.8-27B, 8-bit, takes LoRA adapters29 GB48 GB
27b-4bitQwen3.8-27B, 4-bit, the smallest16 GB32 GB

saetta download picks the largest that fits. Weights come from Hugging Face at pinned revisions and are never part of the repository.

Quickstart

One line to install, one word to start

install
curl -fsSL https://github.com/antonellof/saetta/releases/latest/download/install.sh | sh
saetta
or by hand
# the model that fits this Mac, resumable
saetta download
# Claude Code on it (or pi, opencode)
saetta start claude
Claude Code
saetta start claude
pi
saetta start pi
opencode
saetta start opencode
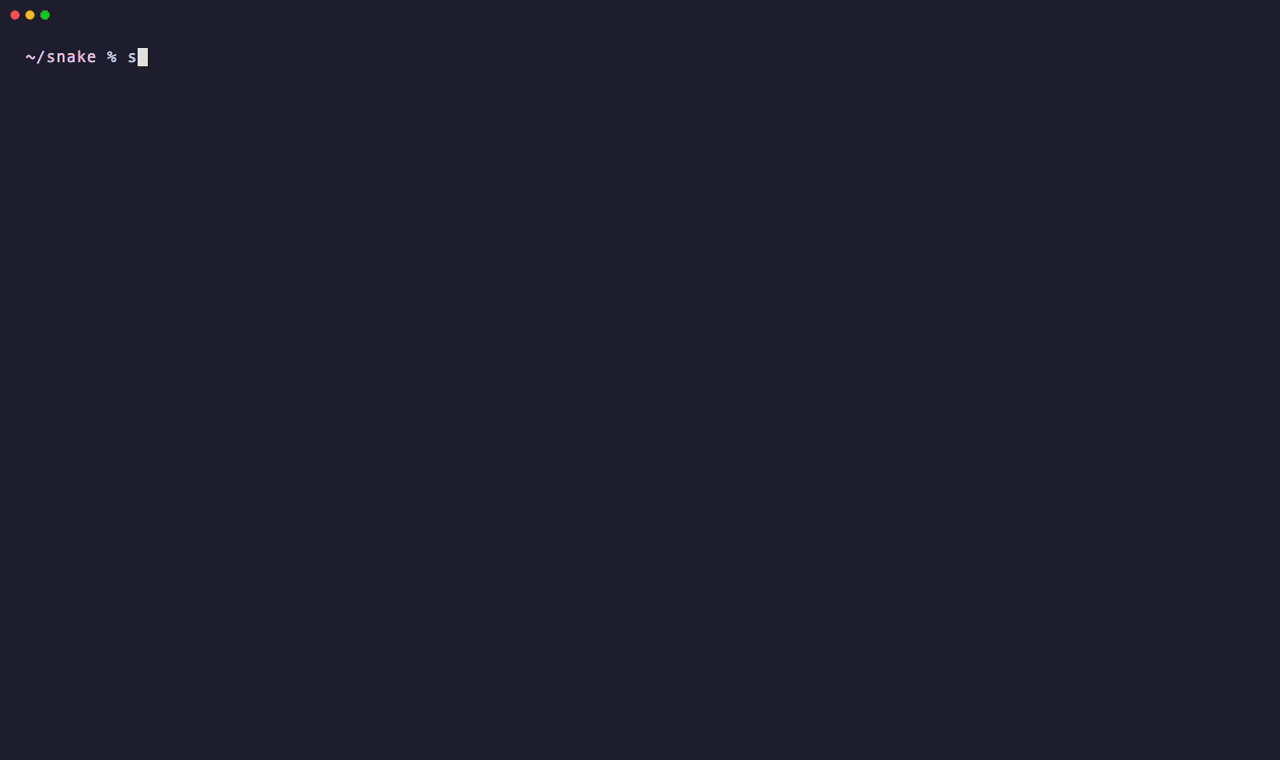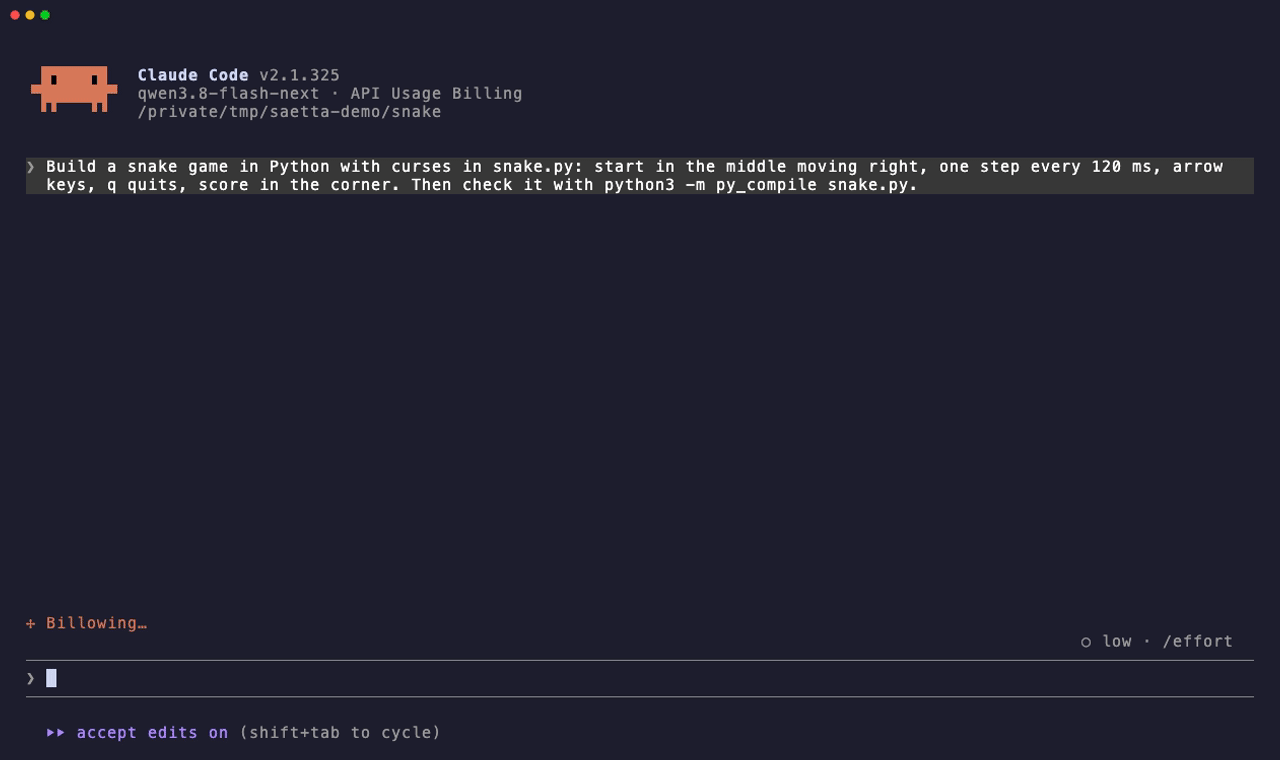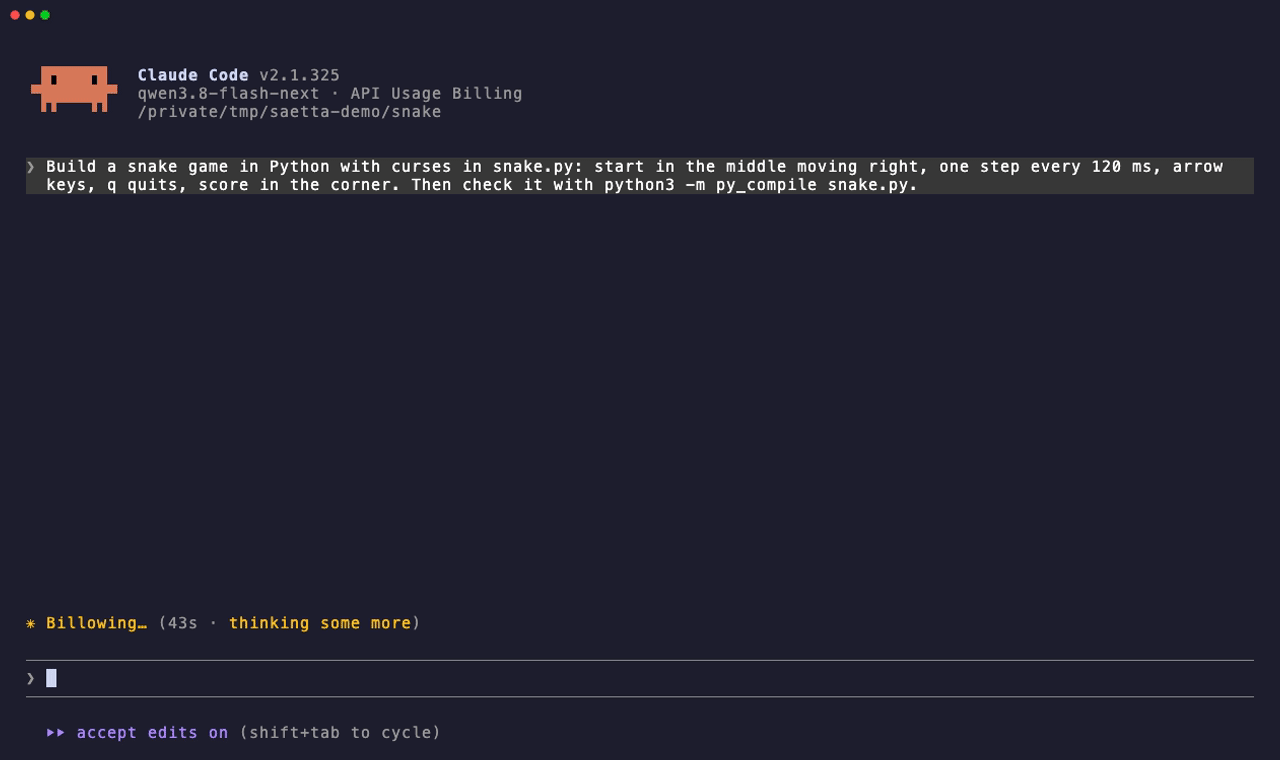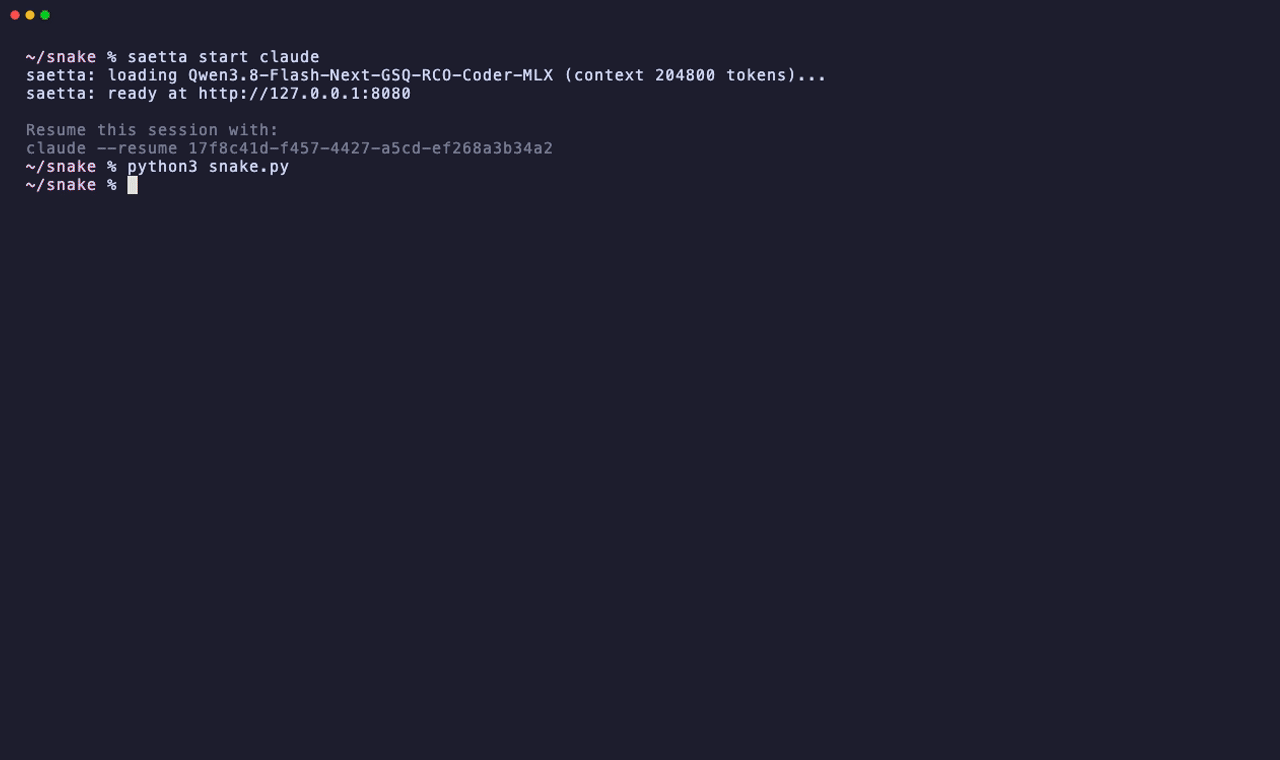
Claude Code running on Saetta writes a snake game in Python, checks it, and the game runs
Claude Code on the local model writes a snake game and checks it. Real time, no cloud.

Any Apple Silicon Mac, M1 or later, with 32 GB of memory or more and macOS 27.2. Tuned and measured on an M5 Max; M1 to M4 are not yet tested on hardware.

FAQ

Local coding models on a Mac

Can I use Claude Code with a local model?

Yes. saetta start claude runs Claude Code against Saetta's Anthropic-compatible API on your own Mac, without editing your Claude Code configuration. pi and opencode work the same way with saetta start pi and saetta start opencode.

Which Mac do I need to run a coding LLM locally?

Any Apple Silicon Mac (M1 or later) with 32 GB of memory or more and macOS 27.2. 32 GB runs Qwen3.8-27B in 4-bit, 36 GB the 27B TURBO fine-tune, 96 GB Qwen3.8-Flash-Next Coder and 128 GB the full Flash-Next. Saetta picks the one that fits.

Does my code leave my machine?

No. The model runs on your Mac and the server listens only on 127.0.0.1, so prompts and code stay local. The only network use is downloading the model weights once from Hugging Face.

Is Saetta free?

Yes. Saetta is open source under the MIT license. The models keep their own licenses: Qwen3.8-27B and the TURBO fine-tune are Apache-2.0, Qwen3.8-Flash-Next uses the Qwen Community License.

How fast is it?

On an M5 Max with 128 GB, Qwen3.8-Flash-Next reads prompts at 1,600 to 1,950 tokens per second and answers at 66 to 85, on par with Strata on a six-request coding-agent workload. Earlier chips run the same kernels on their GPU cores and are slower; they are not yet measured.

Which models does it run?

Qwen3.8-Flash-Next (the pruned Coder variant and the full model) and Qwen3.8-27B in 4-bit and 8-bit, with LoRA adapters and the TURBO fine-tune. Any Qwen3.8-27B GGUF can be converted with saetta import.